Showing posts with label New School. Show all posts

Wednesday, August 25, 2010

I Love Boobies and Information Security


If you work in Information Security, or any form of security for that matter, you're probably used to noticing things. Maybe we just pay a little more attention to the details around us. And if you're working on a college campus, maybe you've noticed the number of people wearing bracelets that say "I love boobies" or "I heart boobies."

Turns out that it is part of a breast cancer awareness campaign and it seems to be quite effective. How effective? So much so that one day while working up in my office I saw three customers in a row come in with the bracelet on. It seemed so rare to me that I asked one of them why there were so many people with the bracelet on. Interestingly, she didn't know of any organized campaign to get people to wear the bracelets and didn't realize that so many people were.
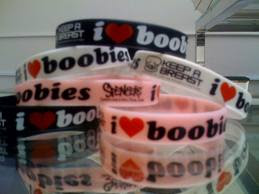
So I decided I should take a moment to figure out how many of our female students on campus are wearing these bracelets. Male students are kind of irrelevant because breast cancer isn't a major concern for them and they probably love boobies for reasons not associated with cancer. So I wanted to know what percentage of female students on campus are wearing this particular kind of bracelet.

This is where reading Douglas Hubbard's book on How to Measure Anything comes in handy. There are some people who would instantly tell me that I wont know unless I take a census of the female students on campus or at least survey about 1000 of them. But since I've read Hubbard's book I know that I don't need as much information or precision as my gut first tells me. I also know that the best way to go measure something is to go out and do it.

So I walked out the door of my building and counted 30 female students at random as I walked from one building to another. If I was able to get close enough to a woman to observe both of her wrists then she was counted, otherwise not. Out of 30, I saw one girl wearing such a bracelet. This very simple observation is enough to tell me that I can be 90% confident that the percentage of female students on campus wearing such a bracelet is between 8% and one one-thousanth of a percent (one observation divided by 7817 female students). I actually decided that I wanted to have more precision so I made a few more observations whenever I had to walk from one building to another.
So there you have it. With a few really simple observations my uncertainty about the number of female students with this bracelet on has been reduced and I can express the measurement as a number. If someone were to ask me, I could say that between one and five percent of the female students on my campus are wearing the bracelet. If the people behind the bracelet were hoping to have ten percent of college girls wearing them then without spending any money or any tremendous amount of time I could tell them that it is unlikely that they met their goal. If the goal was 3% I could tell them that they are close but that additional study is necessary to get a better answer.

So what does this have to with Information Security? Mostly it's just a demonstration that it isn't hard to measure things when you deconstruct the problem and measure it. If we wanted to measure the effectiveness of the I heart boobies bracelets, we have to deconstruct it to find out what the observable characteristics are. In this case, number of students wearing the bracelet. So what if you wanted to measure the effectiveness of your information security awareness program?

First, you have to deconstruct it down to the observable characteristics. If you want to know whether it worked or not, what might you see? One idea that jumps into my head is the number of unattended workstations left unlocked might go down. Sweet. I can observe that, and using the same technique that I used to measure boobie lovers on campus I can get an idea of what percentage of office computers are left unlocked. Or you could send a phishing email to several randomly selected people and count how many answer it. Take before and after measurements and see if there is a noticeable improvement in the numbers.

So what can boobies tell us about Information Security? You can have a lot of fun looking at and measuring things you cant touch.

Monday, June 28, 2010

Book Review - The Failure of Risk Management

Today I finished reading The Failure of Risk Management by Douglas Hubbard (ISBN:978-0-470-38795-5). The book comes in at 259 pages plus an appendix. Overall I found it to be an excellent read.

I should start by saying that I have been a disciple of Hubbard since reading his other book, How to Measure Anything (ISBN: 978-0470110126). In that book Hubbard talks about the variety of things that we just can't measure and then talks about how to measure them. There are a couple of themes that need to be taken away from that book, most important of which is that a measurement is ANYTHING that reduces your uncertainty about something. When you measure length with a ruler you learn that the length of an item is really close to 4 and 3/16 inches, but you could always be more precise. Usually you don't need to. The problem that most of us face when measuring immeasurables is that we can't wrap our heads around the idea that we don't need the same level of precision as we get from a ruler or thermometer.

The Failure of Risk Management takes many of the concepts from How to Measure Anything and applies them to Risk Management. One nice aspect of the book is that it doesn't focus on financial risk or information security risk, or product failure risk. It's just risk, across the board. There is a lot of repeated information in the two books, but I think that How to Measure Anything is more of a practical guide while Failure of Risk Management is more of an explanation of why we should do the stuff he talks about in How to Measure Anything.

The two books are very good companions to each other and I would recommend that security managers should read them both if you really want to see our profession become more than soothsaying and water witching. I think if you're dealing with someone who does not yet believe that Risk Management needs to be quantitative and backed up by experiments and scientific skepticism then they should start with the Failure of Risk Management. On the other hand, if you think we should become more quantitative but think it's too hard then you should start with How to Measure Anything. That will make the challenge seem less difficult. Follow up with the Failure of Risk Management to learn why the way we're currently doing things (heat maps, low/med/high charts) are flawed.

Just like the other book, the Failure of Risk Management throws just enough math at you to be interesting without making you feel like you're sinking. I'll be honest, if you try to read this in two or three long sittings you'll probably become fatigued by some of the math. Take it slowly, especially near the end of the book unless you're already pretty strong with statistics. Having said that, anyone that can follow college algebra should be able to keep up with the most difficult parts of the book. Don't be afraid, jump in.

I enjoyed the book, I give it five stars.

Monday, May 18, 2009

Beta, it's not just for fraternity names

Last week at Secure360 I gave a talk on using monte carlo simulations to deal with unknowns in the calculation of Annualized Loss Expectancy (ALE).  For those of you that need a refresher, the idea behind ALE is that you figure out how much an asset is worth (Asset Value or AV), and you figure out how badly an event would hurt that asset (Exposure Factor or EF).  Then you multiply those by how often it happens (Annual Rate of Occurrence or ARO) to get the Annualized Loss Expectancy (ALE).

In my talk I mentioned using Monte Carlo simulations and why I like them.  You see, I am of the belief that you can't nail any of those numbers (AV, EF, ARO) down precisely so you need to work out a reasonable range or even a slightly unreasonable range as long as you err towards inclusion.  By erring toward inclusion, I mean your range would be unrealistically wide rather than narrow.  Once you have your ranges you can whip up an excel spreadsheet that picks a random number between each of your ranges and spits out the ALE.  Repeat this over 5,000 to 10,000 rows and you've got your simulation.  But a good Monte Carlo simulation is more nuanced than that.

If you just pick a random number between each of your ranges, and there is no skewing of the numbers then after you've done this about 10,000 times you're going to get an average that is shockingly close to what you get if you just take the middle number of each range and multiply.  That is the law of large numbers in action.  What really makes your monte carlo simulations more accurate is that they also take into consideration the shape of your variables.  I'd like to talk about a couple of shapes, and my new favorite formula to use in monte carlo simulations.

For the most part, I have always stuck with two basic shapes, the uniform distribution and the normal distribution.  Uniform distribution is where there is an equally likely chance of any number in the range being the "true" value of the real thing being simulated.  I typically use this on asset value by utilizing the RANDBETWEEN() function.  I know that the asset value falls between x and y and there is an equal chance of any one of those numbers being accurate.  I typically use the normal distribution in cases where I have an average and a reasonable guess about the standard deviation.  For example, if I know that 75% of my users have experienced some phenomena give or take 8% then I will use a normal curve that would spike at 75% and taper off dramatically so that there are almost no values below 67% or above 83%.

But as I have continued to refine my practice of monte carlo simulations, it occurred to me that I need more shapes.  There are variables that don't fit neatly into one of these two shapes, and that is where the beta distribution (http://en.wikipedia.org/wiki/Beta_distribution) comes in.  Beta is able to reproduce a wide variety of shapes that may be more appropriate for your variables.  Let me give you an example.

Let's say one of the threats to your asset is power outage.  One thing you need to know is how often you're going to deal with a power outage in your data center.  Going back over the historical statistics that you've kept, and talking to your server and network people you've all agreed that there will probably be 3 power outages in the data center this year because your maintenance people suck and they are always making changes without telling anyone.  Everyone also agrees that there could be more power outages, but that the odds of having more outages go down quickly as the number increases.  This isn't something that is shaped like a normal curve, this is more of a straight line that is high on the left side and moves down as you go right.  Sure you can punish your data and force it into a normal curve, but instead lets try out our new beta distribution and see if we like that shape better.  In my spreadsheet, under annual rate of occurrence for power outage, I put in =INT(BETAINV(RAND(),1,5,3,8)) and copied that down 500 rows.  Out of the 500 rows, it returned 3 outages per year 347 times, 4 outages 127 times, and 5 outages just 31 times.

I'll let you look at wikipedia to see how the first two numbers (a and b) affect the shape of the distribution.  In a nutshell, if a is bigger than b then the distribution trends upwards.  If b is bigger than a, then the distribution trends downwards.  The difference between a and b is how dramatic that trend is.  If b is much larger than a you get a very L shaped graph where the numbers drop off quickly.  If a=1 and b=2 you get a straight line that trends downward.  The last two numbers in the formula are a bottom and top boundary to put on the distribution.  In my formula above, I say that there will always be at least 3 and never 8 or more.  So if I wanted a straight line reflecting outages of 3 to 8 times per year, then I could use this formula =INT(BETAINV(RAND(),1,2,3,9)).  When I ran that 500 times I got 3 outages 163 times, 4 outages 137 times, 5 = 95, 6 = 66, 7 = 38, and 8 outages 12 times.  In other words, there is only a 1.6% chance that we'll have 8 power outages in one year, but there is a 60% chance that we'll have 3 or 4 outages.  

Play around with some of the other shapes that you can make with your beta distribution.  I just created a spreadsheet where I could play with the a, b, xlow, and xhigh numbers and see how it charts.  I will be honest and tell you that I don't yet know how to calculate what a and b should be in my beta distribution, but I am still really happy because if I can make a distribution that more closely approximates what I expect to see in the real world then my simulations will return better data.  This is one of those areas where we can make our range estimate tighter without spending additional money on research, so even if it isn't exact, it is still good news.  I hope you are able to find value from this as well.

Tuesday, February 3, 2009

Risk analysis: Cost of breaches and rolling your own numbers

In my previous post I talked about how you can apply unknowns to the process of developing your Annual Loss Expectancy (ALE). In the example I gave, we tried to come up with a reasonable estimate of how much money it would cost us per record if some data were exposed. We went through a process of polling our sales force to see what they had on their machines and we estimated how much it would cost us to account for the missing data and notify the affected persons. Why didn't we just use the well known numbers that are thrown around out there? At the time I wrote that, the general consensus was that the average price per record was $197.

But now there is new data and the official price per record has gone up to $202 per record. The good news is that the price per record is not keeping up with inflation! Unless our currency is deflating, in which case we're in even worse shape than we were last year. I had to hand over my personal information and will suffer through the cold sales calls just so that I can read the PDF, but here is a link where someone else has boiled it down. http://treasuryinstitute.org/blog/index.php?itemid=227. There is one specific point that I want you to pay attention to..."lost business is the largest component of the cost" According to the PDF itself, this cost accounts for $139 of the $202 per record. Ouch. This cost is based on an increase in customer churn and diminished ability to recruit future customers. I wish that the PDF had gone into more details of how these numbers were calculated. For example, was the churn number just made up from the individual guesses of each survey respondant? How do we know that the respondant had any clue about the customer churn rate for his or her organization?

But those of us that have read The New School of Information Security know that we shouldn't just be taking these numbers from a vendor and accepting them as gospel. I quote from the good book: "Some people believe that admitting to a security breach will drive away customers. There is research that shows that in most breaches, no more than a small percentage of customers will leave." I also quote from the abstract of this research by Alessandro Acquisti, Allan Friedman, and Rahul Telang titled "Is There a Cost to Privacy Breaches? An Event Study": "We show that there exists a negative and statistically significant impact of data breaches on a company's market value on the announcement day for the breach. The cumulative effect increases in magnitude over the day following the breach announcement, but then decreases and loses statistical significance." Looking at stock market value is a very interesting and valid way to measure the impact of a security breach. If you subscribe to the efficient market hypothesis (semi strong form) then you know that the value of a company's stock already reflects all of the publicly known information about a company. And if you've spent any time reading about predictive markets then you know that a large group of people making decisions with money on the line can results in very good estimates. For example, the Iowa Electronic Market was able to predict the outcome of the 2008 Presidential election to within 1/2 of a percent http://www.biz.uiowa.edu/news/displaystory.cfm?id=2058. So we can say that the stock market will very quickly adjust the price of a company and give us a good indication of the future earnings potential of that company. And the research from Acquisti, Friedman, and Telang indicates that the effect of a data breach is not significant after a few days.

Take a look at this chart of the stock price of TJX. At this point it is difficult to even pick out when exactly they had to make the announcement of their world-famous data breach. In fact, they were forced to make multiple public statements about the data breach over the course of about a year, and the slope of their price increase was about the same as it was for the period of time before their announcement. For the record, the story broke in March of 2007. I tried to see if the same pattern was apparent in the stock charts of Heartland Payment Systems, but the current financial crisis muddies the water. Yes, their stock tanked on the day that the breach was announced, but their stock started a downward trend on October 1st of last year along with just about everyone else so it is hard to say how much of the current price is affected by breach notification and how much is global financial meltdown. If the slope that started on October 1 had kept going, the price of HPY today would be right about where it is right now.

So in the case of these new estimates on the price per record of a data breach, we can now say that over half of the cost is made up of something that we can reasonably doubt. I'm not saying that we should completely discount the cost of lost business, but I do believe that we have reasonable doubt. And that is why I would rather work out my own estimates of the cost of losing data than count on the estimates of someone else. Especially a company that wants to sell me something. I'm not even saying that the report is not valid, but remember that the headline about each record costing an average of $202 is what the company is using to sell your product. Instead, look through the document and see if there are data specific to your company or industry that you can incorporate into your own estimates.

Monday, September 29, 2008

Externalities in IT Security

One of the whims that I've been on lately is trying to apply economic concepts to the practice of Information Security. I'd like to share with you a problem that has been plaguing me for the last few months and an economic approach that might help to fix that problem.

Near the end of every semester, and often around midterm time, professors are asked to provide their students with their grades. Most professors don't want to make their students wait until the official grade shows up on their transcripts and so they post them. Everyone seems to know and agree that grade data should be anonymous, so the grades are not posted by student name. However, there is less understanding that student IDs are also considered non-public information and so posting grades by Student ID is also not acceptable. So every semester, I end up finding grade data posted by Student ID, and in some cases that grade data is put on a web server and the data is then indexed by Google. Hijinks ensue.

So far the approach to combating this problem is to send out messages to all the faculty around the end of the semester reminding them not to post grade by Student ID. However, based on the fact that I keep on having to clean up these messes, I can conclude that the emails are not being read, are being ignored, or the message is being forgotten. Another possibility is that the message is being read and understood, but each professor perceives that the benefit of posting the grades by Student ID outweighs the penalty and thus make a conscious choice to break the rules.

Regardless of what is happening, we can be certain that the way we're dealing with the problem right now is not effective. So I started thinking about the problem like a junior economist, and I decided that this is an example of a negative externality. An externality is an impact (either good or bad) felt by someone that is not involved in the event that caused the impact. A classic example is air pollution. When you buy a product from a factory the factory gets money and you get a product. The factory may also produce smog as part of the production process. I however, got nothing but extra smog. The factory has imparted a negative externality upon me. In the case of posting grades, the professor enjoys a convenient way of posting grades, and the student get their grades faster. However, the university could find itself in violation of federal law (FERPA) and the IT department may have to spend time cleaning up the mess. Posting grades by Student ID imparts a negative externality on the rest of the University.

So how do we deal with externalities in the real world? Well in the case of negative externalities, we can impose government regulation or we can apply taxes. In the case of improperly posting grades online, there is already government regulation in place, but the regulation is against the school, not the individual professor. I believe that we should move the cost closer to the professor. It is well understood in the insurance industry that risk should be assigned to the party that is most able to mitigate it. In this case, the cost of posting grades improperly should be assigned to the group that is most able to prevent it from happening, which is the professors themselves.

So my proposed solution is that we should work out an estimate for the cost of cleaning this up per record and then start billing departments when we have to clean up these messes. In fact, I believe that we could even make this a largely symbolic fine of $1 per record. In most cases a department will be charged less than $50. However, when a dean or department head has to open up their budget and fork over money for something then they might put more pressure on their professors to follow the rules. If the expense went north of $100 then it is almost certain that professors would be pressured to create unique identifiers for their students rather than post grades by Student ID. I'd like to know if anyone else out there has an opinion about this scheme and if other people have had to solve similar problems.

Monday, August 25, 2008

Book Review: The New School of Information Security

The New School of Information Security
Adam Shostack & Andrew Stewart
2008 Pearson Education Inc, ISBN: 0-321-50278-7
160 Pages plus 51 pages of end notes.

Overview
The New School of Information Security is a call to action for Information Security professionals to change the way that we think about information security. For many of us, our approach to information security is dominated by principles such as defense in depth and separation of duties. While this book does not discount those principles, it urges security professionals to start looking to other sciences to help answer questions such as “How much defense in depth is appropriate?” The book employs principles from economics, psychology, and sociology to help explain some of the problems that the Information Security industry faces. Much of the information in this book is interesting and though provoking, but you’ll find that I criticize it for being short on details frequently.

One criticism that I’ve seen in other reviews that I believe is accurate is that the information in this book could have been presented in a pamphlet. I think that it is safe to say that 85% of the meat of this book is in chapter 4. The other chapters simply reinforce the beliefs presented in chapter 4. I also hate the way the endnotes are presented in the book. When the authors make a bold claim, they do not put a number after the sentence so you can easily find their source. Instead you have to flip to the back of the book, find the chapter that you’re reading, then read through all of the quotes until you find the one that you want. My biggest criticism of the book is that it doesn’t really tell me what I should do right now to improve the state of information security. The book tells me to think lofty thoughts but in the meantime my users still give their password to every phisher that writes to them. I think that the book is very interesting, and I think that it is a view into the future of our craft, but don’t expect to come away knowing what your next steps are.

Chapter Description
Chapter 1 is largely an overview of the security state of the Internet. Nothing in this chapter will be particularly educational for a seasoned information security professional, but I don’t believe that the author meant for it to be. This chapter is largely useful for setting the tone of the next two chapters.

Chapter 2 examines the way that we currently respond to the problems presented in chapter 1. It examines the faults of the information security industry and the motivations of all the players: vendors, analysts, hackers, crackers, etc. While this information is interesting, I don’t believe that it is always accurate. For example, on page 31 the author mentions that the CISSP certification “…employs a syllabus that it refers to as ‘the common body of knowledge.’ It amounts to a statement by the certification body of what a security professional should think about. Because of what is left out, it is also an implicit statement about what should not be thought about.” I do not believe that the intent of the CBK is to serve as a compendium of all the relevant knowledge in the information security field. Rather, I believe that the CBK is a collection of the knowledge that (ISC)2 believes all security professionals should know. I believe that the CBK allows that one could specialize in any of the ten domains and gather more detailed information beyond what is present in the CBK. The chapter rightly mentions that most of our problems can be solved by doing a few things really well, but is short on examples. The industry, however, has focused on selling us products to fix problems in other products. We aren’t trying to solve problems at their root, and we often use fear and group think to decide which actions to take.

Chapter 3 talks about the sources of information that are used to create the groupthink and fear discussed in chapter 2. Evidence comes in the form of surveys, vulnerabilities, trade press, and companies each of which has major flaws (such as sampling bias in the case of surveys). They are particularly hard on statistics, especially those well known statistics that everyone can cite but nobody can prove. For example, everyone knows that in our lifetime we are going to swallow a number of spiders while we are sleeping, but nobody can point to a single scientific study where a researcher has watched people sleeping and counted the number of spiders that entered their mouths. In the book the authors point to the well known fact that 50 to 70 percent of breaches are caused by insiders.

Chapter 4 mainly focuses on breach notification and how that information, if shared properly, can be of tremendous value to the security profession. The chapter introduces the concept of Prisoners Dillema from Economics: a situation where two people acting in their own self interest bring about an outcome that is worse for both of them. The authors present evidence that in the security industry, the practice of withholding breach information is acting in our own self interest and deprives the community of valuable information that can be used to create scientifically-tested findings. They talk about the reasons why companies avoid sharing this information and what scientists could do if a large body of this information were available. Another interesting idea that the authors point out is the concept of semi-strong efficiency in the stock market, although they do not use that particular term. Semi-strong efficiency is the belief that the current stock price of a company reflects all of the publicly known information about the company. The authors use this theory and some event analysis of the stock market to support their belief that releasing breach information does not result in significant customer flight.

In chapter 5 the authors introduce other concepts from economics, psychology, and sociology that should be considered when evaluating security problems. Ideas like the Nash Equilibrium, free-rider problems, externalities, risk homeostasis, and agency problems. I found this information to be interesting, but the authors didn’t do a great job of tying these concepts to information security. An example of an externality would be that people who do not patch their computers do not get more spam than the people that do patch. The authors didn’t point that out, instead talking about the pollution generated by SUVs. Externality: people that drive SUVs do not suffer more smog than people who bike to work even though they are a larger contributing factor.

Chapter 6 is all about spending. What we spend money on, what we should spend money on, why we spend money, and how much money we should be spending. This is the first chapter to suggest that we should incorporate concepts like Net Present Value into our security spending. The chapter challenges some of the core beliefs of the information security profession, but is often light on details.

Chapter 7 describes what life will be like in the security field when we’ve all started sharing data and using scientific studies to prove or disprove the effectiveness of our practices. Essentially, life will not be perfect, but it will be better and our industry will be more respected by upper management.

Chapter 8, the last chapter, is a call to action for the information security field to start thinking differently. The authors invite us to start sharing our breach data and using scientific thinking to guide our decision making process. This chapter is pretty short.

Friday, August 22, 2008

New School: How much should I spend to mitigate phishing?

I just finished reading The New School of Information Security by Adam Shostack and Andrew Stewart. I plan on writing a formal book review now that I've made it through the book, but I also wanted to get these thoughts down before they leave my head. In this entry I'm going to attempt to use New School thinking to analyze an event that happened just this week at my organization.

All summer long we've had phising emails sent to our campus and they have pretty much bounced off our users with little effect. However as the school year starts up, we have more people on campus and a phishing message that was sent out this week was able to gather some credentials and those credentials were used to send out spam from our servers.

I responded to the event in a very non-New-School way. I did what my gut said I should do and I stepped up user education efforts. Of course we blocked the affected account, and made some people reset their passwords, but I also had about 300 fliers printed up and distributed around campus reminding people that we don't ask for passwords over email. I've also initiated plans to make some updates to our web pages and automated emails that come out from our department.

Looking back on the whole thing (about two days later) I started trying to take a New School approach to the problem. One of the major ideas expressed in the book that I really agree with is that we need to be more open about events like this and share that information readily instead of keeping it to myself. So I typed up a detailed report and sent it off to my security contacts at other schools in the state.

But now I'd like to address how much money we should spend on mitigating phising attacks in the future. This is where that objective data comes in that we don't have. I don't know how many phishing emails have been sent to universities in the state in the last year. I don't know how many people have responded to the phishing emails, and I don't know how much cost this has imposed on our universities. So I'm not going to be able to answer the question. However, we can look at how the New School would suggest that we answer the question once enough data is present.

This week my school has received about 400 phishing email messages which resulted in about an hour of work for IT staff, and the people that had to reset their passwords. I capitalize an hour of employee time at $50/hour, so each one of those phishing messages cost us about 12.5 cents. However, as I mentioned above, all summer long we were receiving these messages and only had one event. I think there is merit behind the idea that a university is more vulnerable when class is in session than when it is in break. During the summer break I estimate that we had about 2000 phish messages sent to our campus, and that resulted in another $50 worth of loss. So during the breaks a phish message costs us 2.5 cents. With that data we can come up with a Weighted Single Loss Expentancy. (.25)(2.5)+(.75)(12.5) = 10 cents. We can assume that throughout the year, each phish message that we get is going to cost us 10 cents. Therefore, if we receive 10,000 phish messages each year our Annual Loss Expectancy is $1000.

So far this isn't very New School. This is right out of the CISSP Common Body of Knowledge. Here is where things diverge a little bit. One of the things mentioned in the book is a paper by Lawrence Gordon and Martin Loeb that describes how much we should be spending on Information Security. Their paper finds that we should spend somewhere between 25 and 37% of the expected loss on mitigation. So we should spend somewhere between $250 and $370 each year to reduce phishing. This runs counter to the conventional wisdom that says we should spend some amount of money less than $1000 to reduce phishing. One of the principles of Economics is that rational people think at the margin, and Gordon and Loeb point out that after 37% you have hit diminishing returns. In other words, an extra dollar spent on mitigation reduces loss by some number less than one dollar. In fact, if the resource being protected is not very vulnerable, then 37% is far too high. So we could say that it is worth $250/year to reduce phishing.

Now let's bring in my favorite finance concept, Net Present Value. Let's say that I put together a five year project to reduce phishing on campus. I want to spend $50 every year printing fliers. I also want to invest $500 of developer time right now into making changes to our web pages and automated email messages. Is that a good project? The PV of $250 paid each year for five years (5% discount rate) is $1,082.37. So if the PV of my project is less than that, then we're good. $550 in year one, plus $50 each in years 2 through 5 at 5% is $692.66. So it looks like my project is a good idea financially...Maybe.

There are a couple of things that we don't know. Sure we know how much I should spend, but we don't know what I should spend it on. My user education plan might be 10% effective compared to some unknown solution that is 80% effective. Obviously we would put money into the more effective form of mitigation. Another problem to consider (and this is one for the economists) is that the loss expectancy was based on what happened at my university. Well we have a spam firewall and we've already put money into user education, and some of the money spent on that is preventing phishing attacks from working. That money should come out of the $250 a year that we spend...unless an economist would consider that to be sunk cost. I'm not sure. Here is what we would need to answer the question of how much to spend on mitigating phishing positively...
  1. How many phishing emails were sent to undergraduate Universities in Minnesota in the last year?
  2. Is an undergraduate University in Minnesota statistically less vulnerable to phishing when it is in break or is it simply because there are fewer people on campus? It is important to note the qualifiers here. A graduate university may have a more educated population that is less resistant to phishing. Also the population in Minnesota may be more trusting of email than the population in New York.
  3. What are the actual losses suffered by these universities because of phishing?

I'm sure there are other variables to consider, but just these three above can give you a good idea of how far we are from where the authors would like us to be. It would take tremendous information sharing to find out the answer to numbers 1 & 3. It would take years to study to answer question 2. I have to tell you, I get so bogged down in the numbers and variables that I'm not even positive that my analysis above is any good. I'm sure that an expert in economics or finance might read this and say "what a dumbass!" I'm just hoping to be 85% right. I have a lot of learning yet to do.